ChatGPT dot makes AGI feel tangible

I went back to ChatGPT Plus because my tests of Pro had not shown enough additional value for the work I needed to do. More capacity for scheduled tasks or Codex was not what I was looking for. In my own workflows, I had not found the step up in intelligence that would justify staying on Pro. I wanted useful work to progress without having to manage every step.

In October, instructions I had established over the last months became less reliable around the switch from Sol 5.6 to Sol 6.1 in ChatGPT Work. These covered using current sources, preserving knowledge, obtaining approval and checking results. One failure captured the problem: when I asked whether I could delete a conversation, the assistant said yes without first running the agreed process to preserve its useful knowledge.

The frustration: more capability, more supervision

In regular ChatGPT and ChatGPT Work, even basic execution started failing: saving a document became a handoff problem, required fixes stopped at diagnosis, and parts of requested tasks were forgotten while the result was still described as complete.

Over the past months, I had set up workflows for writing, multi-source research, automated tasks for my own websites and knowledge-file maintenance in my Second Brain, my personal knowledge library. Every workflow taught different lessons. The difficulty was knowing which workflows and the capabilities behind them would reliably make my day easier.

The governance rules mattered. Yet having them written down was not the same as having them applied. When I had to remind the assistant to run the process, inspect the right version or finish the agreed fix, I was still carrying the responsibility for execution.

The change: work started moving with me

While trying to resolve these problems, I decided to try dot. A dot is OpenAI’s persistent AI agent for carrying work forward between conversations, using connected tools within its permissions. I upgraded back to Pro to get access and see whether it could make a difference.

When I began using dot, the first days required coaching, and some familiar problems remained. But I started to experience continuity. By continuity, I mean the assistant carrying the agreed work and its context forward while I move between conversations, devices and other things I need to do.

The mechanism was practical: explain the outcome, provide the relevant sources and access, agree the boundaries, then let dot prepare and carry out the work while bringing decisions back to me. Because the work could continue between our conversations, I no longer had to keep a laptop session at the centre of every task.

For teams running websites, CRM and commerce, the comparable opportunity is to reduce the manual coordination between a request, an authorised action and a usable result.

During a tram ride in Kraków, dot submitted ten pages from my website to Google Search Console for indexing, and all ten requests were accepted. I followed progress on my Apple Watch, opening my phone when a decision or approval needed me. That was a real change in how the work fitted into my day. But dot did not turn those successes into a dependable routine. Subsequently, another failed run led me to pause the automation and take the submissions back as manual work.

The usefulness: help across everyday life

Voice was valuable because it let me stay involved in the thinking. I could challenge a recommendation, explain why a distinction mattered or change the emphasis without typing another long prompt. Dot could then continue the preparation. The useful relationship was between my judgment and work that kept progressing.

Travel comparisons helped me make decisions and book two trips. A reminder became useful when an alert actually reached me. These were modest outcomes, but they belonged to the same experience: help across different parts of life, rather than a demonstration confined to one impressive task.

It also made existing knowledge more useful. Material I had already developed about search visibility (answer engine optimisation (AEO) and generative engine optimisation (GEO)) became a German agency brief for a friend, adapted to his website and stripped of my private information. My Mac was off. The knowledge did not need to be recreated; it needed selecting, translating and shaping for someone else to act on.

That breadth, with one assistant carrying context between different tasks, made the idea of artificial general intelligence feel tangible to me.

For a content or CRM team, that suggests a practical direction to test. Can existing research, decisions and approved material become a usable brief without someone repeatedly transferring the context? The value would be in a better handoff and less preparation effort, not simply in producing more documents.

The trust: useful does not mean effortless

Dot did not make every problem disappear. I still had to repeat preferences and correct work that had been called ready too soon.

Dot also helped me resolve problems in my earlier ChatGPT workflows. ChatGPT Work had started saving my instruction to preserve useful knowledge as if the instruction itself were new knowledge. Dot helped tighten the rules so that only meaningful additions should be saved.

The real question is how much useful work is finished, and how much effort still falls back to the person.

I judge the value by the balance of dependable help against the checking and repair it asks of me. Making a consequential decision is a legitimate part of that relationship. Catching a missed instruction should not become a permanent new job. The same distinction applies to authority: preparing work does not automatically permit sending, publishing or sharing it.

The lesson: delegate responsibility in useful increments

For a team, useful delegation has to survive ordinary work, changing requirements and the occasional failure. Judge the whole handoff, including the effort needed to get a result ready for use.

Start with one recurring workflow and a named owner. Agree the desired outcome, the sources the assistant may use, the actions it may take and the decisions that must come back. Compare usable results and total human effort with the current way of working, including setup, review and repair. Expand the responsibility when repeated experience shows a genuine improvement.

Since I started using dot, I haven’t used regular ChatGPT chat or ChatGPT Work. I now work with dot through iMessage or the ChatGPT dot interface. It still needs coaching, but it changed the subscription decision. I returned to Pro to test dot, and I stayed because the value became tangible.


A few fast answers before you act

What is a ChatGPT dot?

A ChatGPT dot is OpenAI’s persistent AI agent for ongoing work across conversations and connected tools. It can continue assigned work, prepare results and bring decisions back to the user. Its access and actions remain subject to permissions and safeguards.

Why can dot make AGI feel tangible?

ChatGPT dot can make the idea of general-purpose AI feel concrete by combining different kinds of help with continuity between conversations. In my experience, it helped with travel decisions and adapting existing knowledge for a friend, while other tasks progressed when I was away from the desk.

Why did ChatGPT Pro become worthwhile for you?

My earlier tests had not given me a clear enough personal reason to keep Pro over Plus. I upgraded again to access dot and test whether it could make a difference. Its voice-led, mobile way of working then made the benefit tangible: I could discuss decisions on the move while useful preparation continued in the background.

What did dot achieve in Google Search Console?

During a tram ride in Kraków, dot submitted ten pages from my website to Google Search Console for indexing, and all ten requests were accepted. I followed progress on my watch and used my phone for decisions or approvals. A later failed run led me to pause the automation and resume manual submissions.

What still required human attention?

In my experience with ChatGPT dot, decisions, approvals and sharing boundaries remained with me. I also had to correct missed instructions and work called ready too soon. That repair effort counts against the benefit of delegation. Preparing a draft does not automatically authorise sending or publishing it, and important outputs still need checking where they will be used.

How should a team test this way of working?

To test AI delegation, choose one recurring workflow with a clear owner, permitted actions and an observable completion standard. Compare usable results and total human effort with the existing workflow across repeated runs, including setup, review and repair. Expand the assistant’s responsibility when those results demonstrate a genuine improvement.
My AI Finished. I Wasn’t Done.

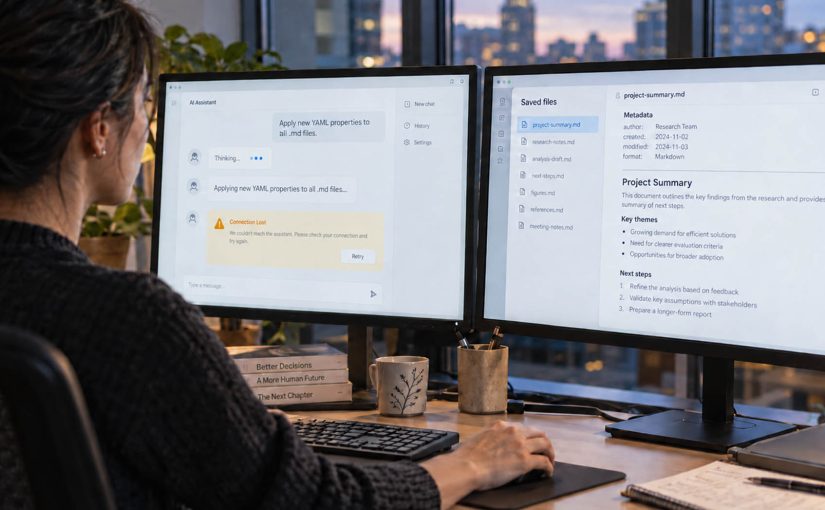
An AI workflow updated 125 files in my knowledge system. Then the chat broke.

The files had changed, but I had no completion message. Fortunately, I was already using two chats: one to develop the strategy and prompt, the other to execute with a more capable model. While the execution chat was unavailable, I used the first to inspect the saved results without repeating the update.

For leaders putting AI into recurring work, the practical question is how much work a team can safely hand over. My recent experiments show why the answer depends on verified delivery, clear ownership and the effort that comes back when a run fails.

The handover: 125 files and a broken chat

This was a controlled update to my Second Brain. My Second Brain is a structured collection of knowledge files that AI can read and update within agreed limits. I used ChatGPT Work with Astra at Extra High to add four YAML metadata fields to each of 125 Markdown files. These are structured properties at the top of a file.

A streaming error prevented a usable completion message, and the Work chat became inaccessible on my phone. Some hours later, back at my desk, I opened a support ticket with OpenAI. Independent of the open ticket, after a six-hour wait, the chat became accessible through my desktop browser, but its visible history was blank. When I asked, the AI said it could still access the history and confirmed completion.

Because the updated files were saved outside the failed conversation, the other chat could inspect them. It confirmed that all 125 contained the four requested fields.

For teams maintaining shared content and reporting, the equivalent requirement is that completed work remains verifiable when the conversation that produced it becomes unavailable.

Consider a regional content update handed from one team to another. The recipient needs to know which records changed, which checks passed and what remains unresolved before deciding whether anything needs to be repeated. Otherwise, even a successful update can leave the next team investigating instead of using it.

The update succeeded. The handover failed. I still had to spend time checking that the work was complete.

The report: plenty of output, more auditing

My weekly campaign-intelligence task exposed a different problem.

One report had 16 campaign cards and six AI items. The audit still rejected its coverage claim. Some video links were marked as usable without confirming that readers could actually watch the campaign videos.

I went through three audit passes on the campaign workflow. A later weekly run still needed more corrections.

The brief sounded straightforward: find relevant campaigns, establish what launched and when, and provide working links to the sources and relevant campaign videos. The report arrived. Then I had to check whether it had met that brief.

An unchecked campaign claim can become an agency briefing error. Catch it after work has started, and brand and agency teams may have to redo the research, recommendation and brief.

Updating the runbook gave the next run better instructions. But I still had to check subsequent reports to see whether the same failures returned.

The real question is how much work remains with the person who supposedly delegated the task to the AI.

The fallback: ten URLs, back on my desk

My website-indexing workflow made that burden concrete.

The intended daily routine was to inspect eligible Ramble pages in Google Search Console, request indexing for up to ten URLs and record the outcomes. This meant submitting requests for Google to consider.

In a batch of ten selected URLs, ChatGPT Work successfully submitted one before Google Search Console returned an error. That left nine unsubmitted. I submitted those manually.

I subsequently defined a recovery path. On the next daily occurrence, the ChatGPT Work cloud browser could not be opened or run for the task. ChatGPT advised me to open a support ticket. But repeated checking and manual execution left too much work with me. So I stopped the workflow without opening a support ticket for this failure.

The technical cause remains unresolved. The operating outcome was clear: this workflow had failed to take the recurring task off my hands.

In a content operation, someone still has to notice the missed work, clear the backlog and decide whether the workflow should continue. A manual fallback can be sensible. It still needs an owner, time and a place in the business case.

The infrastructure: delivering a checked result

My LinkedIn post-performance workflow showed what a more complete delivery could look like. It used authenticated browser access to open the analytics, export the native spreadsheet and inspect its contents. It then recorded the metrics in my maintained Second Brain source, read them back to check that everything had been saved, deleted the exact temporary export and verified its removal.

That sequence of connected access, execution and verification completed successfully. The result was available in the record for subsequent analysis, with the temporary file removed after the checks.

For shared marketing reporting, the same approach would give the next analyst a saved result they could inspect and reuse. Source retrieval, recording and verification would be part of delivery, reducing the work each recipient has to reconstruct.

This chain produced useful work. Reliable repetition and net time saved still need demonstrating.

The model: one part of the service

Comparing ChatGPT Plus and Pro pushed me to separate three questions:

  • Can the model do the thinking the task requires?
  • Can the environment complete the required actions?
  • Does the workflow deliver usable work with an acceptable review burden?

A more capable model may help with difficult reasoning. It does not establish that a browser session will work, a saved result will be checked or a missed delivery will reach the right person.

The same separation belongs in an enterprise buying decision. Model quality, tool access, capacity and operating effort each need assessment. A successful run is evidence for that task and setup; attributing the benefit to a higher subscription tier requires a separate comparison.

The economics: count the work that comes back

I would judge an AI workflow by accepted output and the total human effort needed to obtain it. By accepted output, I mean a result that meets the agreed requirements and is usable for its intended purpose.

If a report needs two repairs before acceptance, it is one delivered report with three attempts behind it. A scheduled run that produces nothing usable still belongs in the record. So does time spent maintaining instructions, recovering access and finishing the task manually.

For a team pilot, three measures would make the business case more useful: acceptance on first delivery, human review and recovery effort, and whether the output was actually used. Missing and abandoned runs must stay visible. Before claiming time savings, count the time spent running, checking and fixing the AI workflow, then compare it with the time the same task took before.

Ownership matters just as much. Someone needs responsibility for missed runs and recovery. Someone needs authority to accept the result. In a small team, those may be the same person. Both responsibilities still need to be explicit.

Controls also take time. If every harmless step needs approval, the task keeps returning to its owner. Checks should sit at consequential decisions, while already-authorised work continues. The result must be worth the money and staff time spent producing, checking and correcting it.

The next step: test the AI handover

The next test is whether a colleague can use the result and handle a failed run without calling the person who built the workflow. That shows whether the team can operate it when its creator is unavailable.

Choose one recurring workflow and define what its recipient needs to accept the result. Name who handles failures, run it through its normal schedule and test a handover to another team member. Record missing and repaired deliveries, actual use and total human effort against the existing process. Expand when the evidence supports the extra scale; narrow or stop when the work keeps coming back.


A few fast answers before you act

Is a scheduled task the same as an AI agent?

No. A schedule determines when work starts. An AI agent uses a model, instructions and tools to pursue a goal and choose its next steps. In ChatGPT Work, a scheduled task can run this kind of workflow. Setting the schedule alone does not make it reliable.

What should count as successful AI delivery?

Successful delivery means the result meets its agreed requirements and is available where the recipient needs it. Record any review, correction or recovery required. A useful result can still have failed its first delivery.

Why keep AI workflow records outside the chat?

Saved results and decision records support continuity when a conversation becomes unavailable. Recovery depends on what was preserved and can be inspected. Another AI’s assurance of completion should be checked against the saved result.

Will a more expensive AI plan make workflows reliable?

A higher price does not establish reliable execution. Evaluate model quality, tools, access, capacity and recovery separately, using comparable work. Attribute a subscription benefit only when the evidence supports it.

How much governance does an AI workflow need?

Match controls to the consequences. Name who accepts the result and who handles failures. Use mechanical checks where possible, reserve approval for decisions that require it and let already-authorised work continue. Measure the review burden alongside errors caught.

What should an enterprise AI pilot measure?

Measure acceptance on first delivery, human review and recovery effort, and practical use against the existing process. Include missing runs, abandoned work and instruction maintenance. Test whether another team member can operate the workflow.

When a Second Brain Becomes an Operating Model

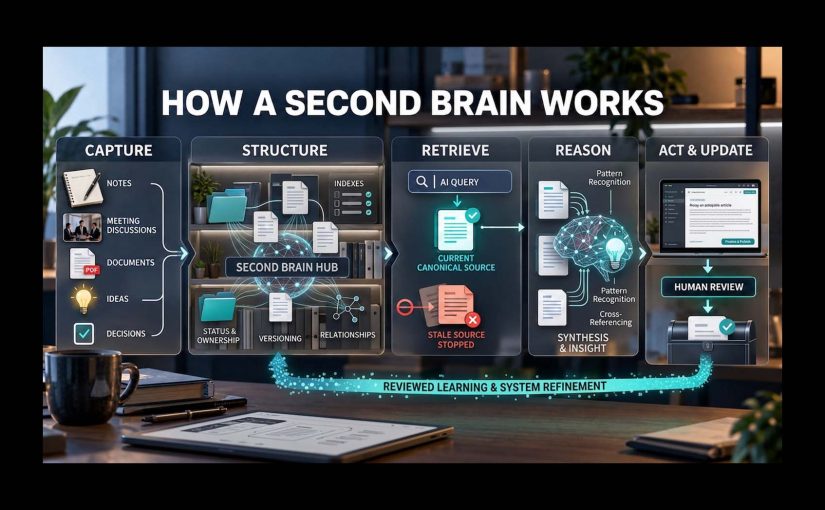
A few weeks ago, I asked ChatGPT a question that required it to read my Second Brain. A Second Brain is a structured personal knowledge system designed to preserve and retrieve useful context. The system answered confidently. The reasoning was coherent. The answer was wrong.

The system had relied on an older cached copy instead of retrieving the current canonical source from Google Drive. By canonical source, I mean the designated current record that should control the answer. This was not a spectacular hallucination. It was a source-selection failure. Intelligent reasoning on the wrong truth is still wrong.

That small failure exposed a much larger enterprise problem. As AI moves from answering questions to maintaining knowledge and taking action, the challenge shifts from finding information to governing what the system may treat as true, what it may change, and when it must stop. I would like to take a moment to explain why that shift matters and where an organization should begin.

The experiment: give AI persistent context

I started building my Second Brain in March 2026. The early work was deliberately unglamorous. I maintained the system meticulously by hand in Obsidian, using separate subject areas, clear file names, consistent conventions, and disciplined decisions about which source was current. I was not trying to build an autonomous agent. I was building a knowledge foundation that I could trust and that would make me AI agnostic.

By late June, I read that ChatGPT could retrieve and reason over that material through Google Drive. So after my summer break, in August, I deliberately enabled controlled read and write access rather than giving the system unrestricted authority. Within roughly a week, the experiment moved toward governed autonomous operation. Tasks such as identifying missing files, flagging duplicate or conflicting versions, updating indexes and maps of content, drafting summaries, and preparing proposed changes for review could proceed without step-by-step prompting, while write access, approval, and human oversight remained explicit.

The foundations took months. Once those foundations existed, the jump from knowledge retrieval to governed autonomous operation happened extraordinarily quickly.

That acceleration is what makes Dan Martell’s video useful. He shows a personal AI system built around persistent files for people, projects, decisions, preferences, and lessons. Meeting transcripts feed the system. A scheduled task can identify missing files, consolidate duplicates, update maps of content, and flag strategic items. The attraction is not simply better note-taking. It is context that an AI can maintain and use.

His demonstration is a helpful picture of the destination, not evidence that the enterprise problem is solved. A personal system has one principal owner and a comparatively small permission boundary. An enterprise has contested facts, inherited access, regulatory duties, multiple systems of record, and decisions whose consequences spread across teams and customers.

The mechanism: memory becomes operational

I use enterprise operating memory here as shorthand for the shift. An enterprise operating memory is a governed capability that turns selected organizational knowledge into source-traceable context for people and AI agents, while controlling who can retrieve it and when it may be updated or used to act.

Organizational memory has been studied for decades, and current AI-enabled platforms already combine enterprise search, permission-aware retrieval, knowledge graphs, citations, agent memory, and actions. What those components do not solve on their own is the operating model that decides which source controls, how conflicts are handled, and who is accountable for reviewing, approving, reversing, and learning from a harmful change.

At its simplest, the mechanism is a loop. The system retrieves relevant material, reasons across it, drafts a conclusion or action, and, if authorized, writes the result back or acts in another system. Because the system can write its interpretation back into the knowledge layer, one source-selection error can become persistent and influence later decisions.

For a consumer-experience organization, the same mechanism could connect brand standards, product data, consent rules, campaign decisions and performance history.

Suppose the system retrieves an older consent rule that is no longer current while preparing a global website update. In read-only mode, the error creates a flawed summary. With write access, it could spread the rule to a campaign brief, delivery backlog, or customer-facing configuration. A source-status check should reject the outdated version. A staged comparison should show the proposed change, and the privacy owner should approve or stop it. The same system that saves time can also magnify weak source controls.

That creates more leverage than enterprise search. Search finds what exists. A knowledge graph connects it. Agent memory preserves context. Operating memory governs what is current, why it is authoritative, what it replaces, and under what bounded authority AI may change it.

Here, executable knowledge does not mean literal code. It means knowledge has become an operational input capable of shaping a decision or triggering an action.

The failure: retrieval is not truth

My stale-file incident was minor and reversible. Its value was diagnostic. The system had access to relevant material, but relevance was not enough. It needed a rule that required the current canonical source for that task and a safe response that flagged the uncertainty and stopped rather than guessing when it could not determine which source was authoritative.

The incident changed how I work. I now treat source selection as a control decision, not an invisible retrieval step, and I require the current canonical source before giving high-impact answers. In my Second Brain, I use YAML properties, structured metadata at the top of each file, to record status, owner, version, effective date, review date, canonical-source designation, and links to earlier or replaced versions. If those properties are missing, the file’s date and time may help identify the likely latest version, but recency does not prove authority. For high-impact tasks, unclear source status should trigger a stop, not a guess. This is the practical pattern I trust most: turn failure modes into governance controls.

Source citations and access permissions help, but neither proves that an answer is correct. A citation shows where a statement came from, not whether that source was approved, current, or controlling. Permission-aware retrieval shows that a person can access something, not that the material is appropriate for every purpose.

The real question is not whether AI can read organizational knowledge, but whether it can be trusted to maintain and act on it.

My stance is simple: organizations should treat AI-maintained knowledge as a controlled operational asset, not as a smarter search box.

The value: remove the coordination tax

Coordination tax is the time people lose finding owners, rebuilding context, reconciling versions, and repeating decisions.

The business case is not that expertise becomes unnecessary. It is that expertise no longer has to be the bottleneck for reconstructing context.

Imagine a specialist is absent during a critical decision. An authorized colleague could ask for the current state, the decisions already made, the rationale behind them, open issues, safe next actions, and matters that still require approval. The system could assemble that context from governed sources, while the specialist or accountable owner remains responsible for judgment.

Or consider a manager preparing a decision across product, analytics, privacy, brand, localization, and marketing technology. Today, the manager may spend days finding the right people, reconciling versions, and rebuilding the history. An operating-memory layer could draft the status, expose contradictions, identify dependencies, and prepare the decision narrative. The relevant specialists would still validate the consequential parts.

In August 2026, Google submitted the winning $10 million bid for a Spirit Airlines data package containing roughly 100 million emails and 500 million Microsoft Teams messages, alongside source code and extensive operational and financial records. The proposed transfer was subject to court approval and de-identification, and the price covered the complete package, not the messages alone. Even so, the bid signals that the decisions, workflows, and institutional context buried inside enterprise systems are becoming valuable inputs for AI. For a living company, the greater opportunity is not to sell that memory, but to govern and reuse it for its own benefit.

That is where the potential productivity gain sits: less context reconstruction, fewer repeated explanations, and faster handoffs. It is a reduction in coordination tax, not a promise to remove people.

AI helps the organization reuse what it already knows. People create what it needs to know next.

The countercase: scale magnifies weak controls

The strongest objection is also the reason to act carefully. A successful personal Second Brain does not transfer its safety to an enterprise. It transfers the organization’s stale documents, overshared folders, conflicting policies, ambiguous ownership, and missing decision history into a probabilistic system with tool access.

Permission-aware retrieval can reproduce bad permissions. A current index can faithfully retrieve a document that was never authoritative. A cited answer can still apply the wrong policy version. An approval prompt can become a rubber stamp. A write can create a circular knowledge loop in which AI stores a conclusion and later cites that conclusion as independent evidence.

Unwritten expertise creates another limit. Not everything important has been captured, and not every exception can be inferred from documents. The system represents selected organizational knowledge; it does not contain everything the organization knows.

This does not argue for keeping AI read-only forever. It argues for earning autonomy one action type at a time. Reading is different from drafting. Drafting is different from staging a visible change. Staging is different from publishing, deleting, or triggering a customer-facing action.

The controls: make authority explicit

The practical design is federated. Federated means domain and team spaces can remain close to the people who understand them while shared rules govern how knowledge becomes authoritative and how AI may use it. The alternative is either hundreds of disconnected personal brains or one unrestricted corporate brain.

Six controls matter first:

  1. Truth: Name the canonical source, accountable owner, status, effective date, review date, and superseded version.
  2. Access: Enforce identity, authorization, sensitivity, and legitimate need at retrieval time. Seniority alone is not a permission model.
  3. Authority: Separate permission to read, draft, stage, write, publish, delete, and act. Let downstream systems enforce authorization.
  4. Provenance: Preserve the exact source versions, model and tool context, policy checks, approvals, output, and resulting action for material changes.
  5. Verification: Test whether the source is current and controlling, expose unresolved conflicts, and require the system to abstain when evidence is insufficient.
  6. Escalation: Assign a human owner with the competence, time, authority, and ability to stop or reverse the action.

Put those controls into practice with one team and one bounded, reversible workflow, such as producing a weekly cross-market website status brief. Before starting, record the current cycle time, coordination effort, unresolved source conflicts, and rework caused by stale information. First, let AI retrieve and cite named canonical sources. Then let it draft the brief and stage proposed updates to a decision log for an accountable owner to approve. Measure canonical-source selection, correction rates, and time saved against the baseline. Only after agreed thresholds are met should low-risk maintenance run autonomously. Publishing, deletion, and customer-facing changes should remain approval-gated and reversible.

When AI moves from retrieving information to changing organizational state, governance rules must be enforced at the moment the system retrieves, writes, or acts.

The starting point: govern truth before action

The purpose of the pilot is not merely to prove that AI can retrieve and draft. It is to prove that the organization can identify authoritative sources, measure improvement against a baseline, expose uncertainty, assign approval, and reverse a bad change before scaling. Once those foundations hold, the harder question becomes: what happens when organizational knowledge becomes executable, not merely searchable?

The practical takeaway is this: start by governing truth before granting autonomy. In one bounded, reversible workflow, identify the canonical sources, assign accountable owners, define freshness and access rules, and measure how often the system selects the correct source. Then separate read, draft, stage, write, publish, delete, and action authority; require human approval for consequential changes; preserve provenance; and make every material change reversible. Only expand autonomous permissions when the pilot shows that the system reliably selects authoritative sources, exposes uncertainty, reduces coordination effort, and can be stopped or corrected when it fails.


A few fast answers before you act

What is an enterprise operating memory?

An enterprise operating memory is a governed, federated capability that makes selected organizational knowledge available as permission-aware, source-traceable context for people and AI agents, with explicit controls over updates and actions.

Is it just enterprise search or retrieval-augmented generation (RAG)?

No. Search and retrieval-augmented generation can find and synthesize relevant content. An operating-memory model also governs source authority, lifecycle, write permissions, verification, escalation, and the consequences of changing organizational knowledge.

Does it replace specialists?

No. It can reduce the time specialists and colleagues spend reconstructing context, but specialists remain essential for creating new knowledge, interpreting exceptions, and validating consequential decisions.

What should organizations govern first?

Organizations should first define canonical sources, accountable owners, source status, freshness rules, access boundaries, and the conditions under which the system must expose a conflict or abstain.

Where should an enterprise pilot start?

Start with one team and one bounded, reversible workflow inside the shared governance model. Record the current cycle time, coordination effort, source conflicts, and rework before the pilot begins. Progress from retrieval to drafting and staged changes with named approval. Add low-risk autonomous maintenance only when agreed accuracy and control thresholds are met. Scale only when the measured gains persist and the governance model continues to hold.

What is the biggest failure mode?

The biggest failure mode is authoritative-looking action based on knowledge that is relevant but stale, incomplete, noncanonical, or inappropriate for the user’s purpose. Good reasoning cannot rescue the wrong source of truth.