When a Second Brain Becomes an Operating Model

A few weeks ago, I asked ChatGPT a question that required it to read my Second Brain. A Second Brain is a structured personal knowledge system designed to preserve and retrieve useful context. The system answered confidently. The reasoning was coherent. The answer was wrong.

The system had relied on an older cached copy instead of retrieving the current canonical source from Google Drive. By canonical source, I mean the designated current record that should control the answer. This was not a spectacular hallucination. It was a source-selection failure. Intelligent reasoning on the wrong truth is still wrong.

That small failure exposed a much larger enterprise problem. As AI moves from answering questions to maintaining knowledge and taking action, the challenge shifts from finding information to governing what the system may treat as true, what it may change, and when it must stop. I would like to take a moment to explain why that shift matters and where an organization should begin.

The experiment: give AI persistent context

I started building my Second Brain in March 2026. The early work was deliberately unglamorous. I maintained the system meticulously by hand in Obsidian, using separate subject areas, clear file names, consistent conventions, and disciplined decisions about which source was current. I was not trying to build an autonomous agent. I was building a knowledge foundation that I could trust and that would make me AI agnostic.

By late June, I read that ChatGPT could retrieve and reason over that material through Google Drive. So after my summer break, in August, I deliberately enabled controlled read and write access rather than giving the system unrestricted authority. Within roughly a week, the experiment moved toward governed autonomous operation. Tasks such as identifying missing files, flagging duplicate or conflicting versions, updating indexes and maps of content, drafting summaries, and preparing proposed changes for review could proceed without step-by-step prompting, while write access, approval, and human oversight remained explicit.

The foundations took months. Once those foundations existed, the jump from knowledge retrieval to governed autonomous operation happened extraordinarily quickly.

That acceleration is what makes Dan Martell’s video useful. He shows a personal AI system built around persistent files for people, projects, decisions, preferences, and lessons. Meeting transcripts feed the system. A scheduled task can identify missing files, consolidate duplicates, update maps of content, and flag strategic items. The attraction is not simply better note-taking. It is context that an AI can maintain and use.

His demonstration is a helpful picture of the destination, not evidence that the enterprise problem is solved. A personal system has one principal owner and a comparatively small permission boundary. An enterprise has contested facts, inherited access, regulatory duties, multiple systems of record, and decisions whose consequences spread across teams and customers.

The mechanism: memory becomes operational

I use enterprise operating memory here as shorthand for the shift. An enterprise operating memory is a governed capability that turns selected organizational knowledge into source-traceable context for people and AI agents, while controlling who can retrieve it and when it may be updated or used to act.

Organizational memory has been studied for decades, and current AI-enabled platforms already combine enterprise search, permission-aware retrieval, knowledge graphs, citations, agent memory, and actions. What those components do not solve on their own is the operating model that decides which source controls, how conflicts are handled, and who is accountable for reviewing, approving, reversing, and learning from a harmful change.

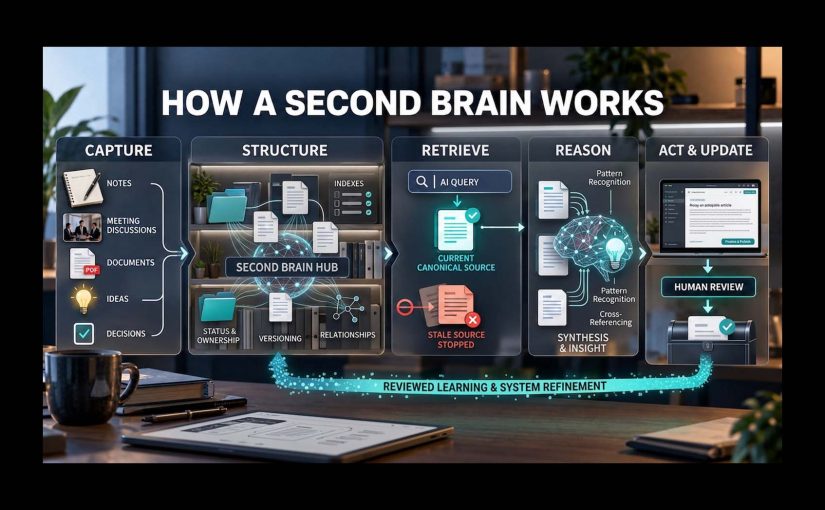
At its simplest, the mechanism is a loop. The system retrieves relevant material, reasons across it, drafts a conclusion or action, and, if authorized, writes the result back or acts in another system. Because the system can write its interpretation back into the knowledge layer, one source-selection error can become persistent and influence later decisions.

For a consumer-experience organization, the same mechanism could connect brand standards, product data, consent rules, campaign decisions and performance history.

Suppose the system retrieves an older consent rule that is no longer current while preparing a global website update. In read-only mode, the error creates a flawed summary. With write access, it could spread the rule to a campaign brief, delivery backlog, or customer-facing configuration. A source-status check should reject the outdated version. A staged comparison should show the proposed change, and the privacy owner should approve or stop it. The same system that saves time can also magnify weak source controls.

That creates more leverage than enterprise search. Search finds what exists. A knowledge graph connects it. Agent memory preserves context. Operating memory governs what is current, why it is authoritative, what it replaces, and under what bounded authority AI may change it.

Here, executable knowledge does not mean literal code. It means knowledge has become an operational input capable of shaping a decision or triggering an action.

The failure: retrieval is not truth

My stale-file incident was minor and reversible. Its value was diagnostic. The system had access to relevant material, but relevance was not enough. It needed a rule that required the current canonical source for that task and a safe response that flagged the uncertainty and stopped rather than guessing when it could not determine which source was authoritative.

The incident changed how I work. I now treat source selection as a control decision, not an invisible retrieval step, and I require the current canonical source before giving high-impact answers. In my Second Brain, I use YAML properties, structured metadata at the top of each file, to record status, owner, version, effective date, review date, canonical-source designation, and links to earlier or replaced versions. If those properties are missing, the file’s date and time may help identify the likely latest version, but recency does not prove authority. For high-impact tasks, unclear source status should trigger a stop, not a guess. This is the practical pattern I trust most: turn failure modes into governance controls.

Source citations and access permissions help, but neither proves that an answer is correct. A citation shows where a statement came from, not whether that source was approved, current, or controlling. Permission-aware retrieval shows that a person can access something, not that the material is appropriate for every purpose.

The real question is not whether AI can read organizational knowledge, but whether it can be trusted to maintain and act on it.

My stance is simple: organizations should treat AI-maintained knowledge as a controlled operational asset, not as a smarter search box.

The value: remove the coordination tax

Coordination tax is the time people lose finding owners, rebuilding context, reconciling versions, and repeating decisions.

The business case is not that expertise becomes unnecessary. It is that expertise no longer has to be the bottleneck for reconstructing context.

Imagine a specialist is absent during a critical decision. An authorized colleague could ask for the current state, the decisions already made, the rationale behind them, open issues, safe next actions, and matters that still require approval. The system could assemble that context from governed sources, while the specialist or accountable owner remains responsible for judgment.

Or consider a manager preparing a decision across product, analytics, privacy, brand, localization, and marketing technology. Today, the manager may spend days finding the right people, reconciling versions, and rebuilding the history. An operating-memory layer could draft the status, expose contradictions, identify dependencies, and prepare the decision narrative. The relevant specialists would still validate the consequential parts.

In August 2026, Google submitted the winning $10 million bid for a Spirit Airlines data package containing roughly 100 million emails and 500 million Microsoft Teams messages, alongside source code and extensive operational and financial records. The proposed transfer was subject to court approval and de-identification, and the price covered the complete package, not the messages alone. Even so, the bid signals that the decisions, workflows, and institutional context buried inside enterprise systems are becoming valuable inputs for AI. For a living company, the greater opportunity is not to sell that memory, but to govern and reuse it for its own benefit.

That is where the potential productivity gain sits: less context reconstruction, fewer repeated explanations, and faster handoffs. It is a reduction in coordination tax, not a promise to remove people.

AI helps the organization reuse what it already knows. People create what it needs to know next.

The countercase: scale magnifies weak controls

The strongest objection is also the reason to act carefully. A successful personal Second Brain does not transfer its safety to an enterprise. It transfers the organization’s stale documents, overshared folders, conflicting policies, ambiguous ownership, and missing decision history into a probabilistic system with tool access.

Permission-aware retrieval can reproduce bad permissions. A current index can faithfully retrieve a document that was never authoritative. A cited answer can still apply the wrong policy version. An approval prompt can become a rubber stamp. A write can create a circular knowledge loop in which AI stores a conclusion and later cites that conclusion as independent evidence.

Unwritten expertise creates another limit. Not everything important has been captured, and not every exception can be inferred from documents. The system represents selected organizational knowledge; it does not contain everything the organization knows.

This does not argue for keeping AI read-only forever. It argues for earning autonomy one action type at a time. Reading is different from drafting. Drafting is different from staging a visible change. Staging is different from publishing, deleting, or triggering a customer-facing action.

The controls: make authority explicit

The practical design is federated. Federated means domain and team spaces can remain close to the people who understand them while shared rules govern how knowledge becomes authoritative and how AI may use it. The alternative is either hundreds of disconnected personal brains or one unrestricted corporate brain.

Six controls matter first:

  1. Truth: Name the canonical source, accountable owner, status, effective date, review date, and superseded version.
  2. Access: Enforce identity, authorization, sensitivity, and legitimate need at retrieval time. Seniority alone is not a permission model.
  3. Authority: Separate permission to read, draft, stage, write, publish, delete, and act. Let downstream systems enforce authorization.
  4. Provenance: Preserve the exact source versions, model and tool context, policy checks, approvals, output, and resulting action for material changes.
  5. Verification: Test whether the source is current and controlling, expose unresolved conflicts, and require the system to abstain when evidence is insufficient.
  6. Escalation: Assign a human owner with the competence, time, authority, and ability to stop or reverse the action.

Put those controls into practice with one team and one bounded, reversible workflow, such as producing a weekly cross-market website status brief. Before starting, record the current cycle time, coordination effort, unresolved source conflicts, and rework caused by stale information. First, let AI retrieve and cite named canonical sources. Then let it draft the brief and stage proposed updates to a decision log for an accountable owner to approve. Measure canonical-source selection, correction rates, and time saved against the baseline. Only after agreed thresholds are met should low-risk maintenance run autonomously. Publishing, deletion, and customer-facing changes should remain approval-gated and reversible.

When AI moves from retrieving information to changing organizational state, governance rules must be enforced at the moment the system retrieves, writes, or acts.

The starting point: govern truth before action

The purpose of the pilot is not merely to prove that AI can retrieve and draft. It is to prove that the organization can identify authoritative sources, measure improvement against a baseline, expose uncertainty, assign approval, and reverse a bad change before scaling. Once those foundations hold, the harder question becomes: what happens when organizational knowledge becomes executable, not merely searchable?

The practical takeaway is this: start by governing truth before granting autonomy. In one bounded, reversible workflow, identify the canonical sources, assign accountable owners, define freshness and access rules, and measure how often the system selects the correct source. Then separate read, draft, stage, write, publish, delete, and action authority; require human approval for consequential changes; preserve provenance; and make every material change reversible. Only expand autonomous permissions when the pilot shows that the system reliably selects authoritative sources, exposes uncertainty, reduces coordination effort, and can be stopped or corrected when it fails.


A few fast answers before you act

What is an enterprise operating memory?

An enterprise operating memory is a governed, federated capability that makes selected organizational knowledge available as permission-aware, source-traceable context for people and AI agents, with explicit controls over updates and actions.

Is it just enterprise search or retrieval-augmented generation (RAG)?

No. Search and retrieval-augmented generation can find and synthesize relevant content. An operating-memory model also governs source authority, lifecycle, write permissions, verification, escalation, and the consequences of changing organizational knowledge.

Does it replace specialists?

No. It can reduce the time specialists and colleagues spend reconstructing context, but specialists remain essential for creating new knowledge, interpreting exceptions, and validating consequential decisions.

What should organizations govern first?

Organizations should first define canonical sources, accountable owners, source status, freshness rules, access boundaries, and the conditions under which the system must expose a conflict or abstain.

Where should an enterprise pilot start?

Start with one team and one bounded, reversible workflow inside the shared governance model. Record the current cycle time, coordination effort, source conflicts, and rework before the pilot begins. Progress from retrieval to drafting and staged changes with named approval. Add low-risk autonomous maintenance only when agreed accuracy and control thresholds are met. Scale only when the measured gains persist and the governance model continues to hold.

What is the biggest failure mode?

The biggest failure mode is authoritative-looking action based on knowledge that is relevant but stale, incomplete, noncanonical, or inappropriate for the user’s purpose. Good reasoning cannot rescue the wrong source of truth.
Genspark: Can It Replace 11 AI Subscriptions?

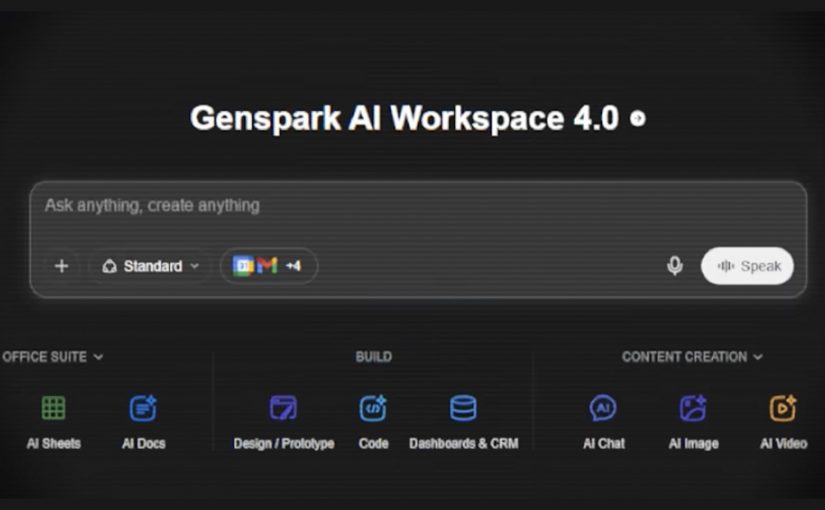
A content workflow is shown using 11 AI logins, 11 separate subscriptions, and 11 different places where files can disappear.

Genspark is presented as the answer: an all-in-one AI workspace. An all-in-one AI workspace is a shared environment that combines models, agents and production tools around one deliverable.

The useful enterprise lesson is not that one product has made 11 subscriptions obsolete. It is that the next productivity gain may come from carrying context across the work, and leaders should test that before adding another specialist AI tool.

The demo: six deliverables, one working context

The demo covers many different outputs: the video reports a week of back-and-forth with the designer to produce a visual identity and a breakdown of raw footage into structured assets completed in minutes. Those are creator-demo claims, not independent performance benchmarks, and the outputs shown still reflect a human-in-the-loop workflow, including review and refinement before final use. They demonstrate breadth of capability, but not repeatable enterprise-grade quality in production environments.

The operating implication is more useful than the spectacle. When the brief, assets and prior decisions remain available to the next task, less work is spent re-explaining intent, moving files and rebuilding context.

The mechanism: context travels with the work

Four days after the video was published, Genspark announced Workspace 6.0 with four layers: SecondBrain as memory; Super Agent as the intelligence engine; a tools layer combining Build Suite for applications, automations and custom tools, Office Suite for slides, documents and spreadsheets, and Content Suite for images, video and campaign assets; and GenTeam for collaboration between people and agents. The mechanism is an orchestration layer. An orchestration layer retains context, selects capabilities and sequences work across models and tools so the user manages the outcome rather than every transfer.

The wider context is a shift from buying isolated AI capabilities to governing a workspace that carries context across a job.

This matters because every handoff creates another opportunity to lose information, introduce a version mismatch or repeat work. Reducing those handoffs can shorten cycle time and lower rework because the next task starts with more of the approved context intact.

The value: fewer handoffs, not magic

The video calls the hidden cost the “tab tax”. The tab tax is the time and attention lost when people switch tools, re-upload assets, restate instructions and reconcile outputs. In an enterprise, that tax also includes access requests, version confusion and approval loops.

The claims that 80% of the work is coordination and that Genspark covers 95% of the production arc are not decision-grade measures. A proper baseline should count elapsed cycle time, active working time, handoffs, rework rounds, accepted outputs and the full cost of the current toolchain.

Consolidation of the baseline creates value only when improvements occur without degrading quality or control.

The enterprise limit: one workspace is not one stack

An AI workspace is not a system of record. A system of record is the authoritative, governed home for a particular class of business data or content. The better enterprise position is clear: use an AI workspace as an orchestration layer around governed systems, not as a replacement for them.

In a MarTech environment, product data, approved assets, consent status, customer profiles and published content still need governed homes such as PIM, DAM, consent, CIAM, CDP and CMS platforms. The workspace may prepare, transform or assemble work, but approved outputs must return to the correct system with source and ownership intact.

Persistent context is also both the attraction and the risk. It means teams don’t have to keep re-uploading the same information, but it also means more data is stored and shared in one place, which increases governance risk. Before scaling, teams need to verify retention, model access, data residency, permissions, auditability, output rights and how integrations work. That makes governance part of the value case, not an afterthought. The real question is whether one governed workspace can remove enough handoffs to improve cycle time and accepted-output quality without weakening control.

Ownership: one workflow still needs many owners

A unified interface does not create unified accountability. The business owner still defines the outcome, platform and IT teams determine integration and security, legal and data-governance teams set usage boundaries, and brand or content operations define the approved inputs and review standard. Procurement only captures savings when redundant tools are actually retired.

Without those decisions, an all-in-one workspace can become one more tab rather than the tab that removes the others. Adoption should focus on specific roles and repeatable workflows, not giving everyone access and hoping a prompt library creates value.

The action: pilot one handoff-heavy workflow

Pick one recurring deliverable that uses several tools and owners. Record the current baseline. Give the workspace controlled access to approved inputs. Run enough repeats to see if results are reliable, not just new. Measure accepted output, not raw output, including the human correction and approval work that remains.

The takeaway: do not buy an all-in-one AI workspace because its feature list is longer. Pilot it where repeated context transfer is already measurable, keep governed systems as the source of truth, and retire specialist tools only when the workflow produces accepted work faster, at lower total cost, without weaker control.


A few fast answers before you act

What is an all-in-one AI workspace?

An all-in-one AI workspace combines multiple AI models, agents and production tools in one environment so work can move from request to deliverable with fewer manual transfers.

Does Genspark replace 11 AI subscriptions?

Genspark does not replace 11 AI subscriptions as a general rule. Eleven was the number in one creator’s workflow; the tools any team can retire depend on output quality, usage, integration, governance and total cost.

How is Genspark different from a chatbot?

Genspark is designed to coordinate models and tools to produce artefacts such as slides, documents, images, video, code and websites, rather than stopping at a conversational answer.

Can an AI workspace replace an enterprise MarTech stack?

An AI workspace cannot replace an enterprise MarTech stack. It may orchestrate work around CMS, DAM, PIM, CRM, CDP, consent and other platforms, but those governed systems should remain the authoritative sources and destinations.

What should an enterprise pilot measure?

An enterprise pilot should compare cycle time, handoffs, rework, accepted-output rate, human review effort, total cost and control failures against the current workflow.

What is the biggest consolidation risk?

The biggest AI-tool consolidation risk is exchanging visible tool fragmentation for hidden dependence on one vendor’s model routing, credits, data handling and integration boundaries.

When AI Starts Shopping for Us

A shopper does not type “treadmill” anymore.

They ask for a treadmill that is good for indoor marathon training, easy on the knees, and not too expensive.

That small shift changes the whole commerce model. The consumer is no longer moving through a store, page by page, filter by filter, until they find a product. The consumer is bringing intent, constraints, context, and comparison logic into one AI-led interaction.

Agentic commerce is commerce where AI agents help consumers move from intent to action, including discovery, comparison, recommendation, checkout, and post-purchase support.

From discovery to decision – the new shopping baseline

Google’s “From Discovery to Delivery” demo is useful because it does not start with a store. It starts with a runner’s need.

The runner uses AI Mode in Search, Gemini, Lens, YouTube, and product evaluation to move from training intent to shopping decision. The important point is not that Google has another AI demo. The important point is that the old journey has been compressed.

The mechanism is simple: the agent holds the shopper’s intent, constraints, product evidence, comparison logic, and action handoff in one flow.

For enterprise teams, this is where content, product data, consent, analytics, service, and checkout stop being separate workstreams.

Because the agent can connect the shopper’s question to product evidence, policy confidence, and purchase action, the experience feels less like browsing and more like being guided to a decision.

This creates the super-empowered consumer.

The super-empowered consumer is a shopper who uses a personal AI layer to research, compare, interpret, and act faster than any single brand interface.

The stance is clear: agentic commerce is not another campaign surface, it is becoming the default operating layer for consumer experience.

UCP – the rails for agentic commerce

Universal Commerce Protocol is an open standard that lets AI surfaces, merchants, and payment providers work together across commerce actions such as discovery, cart building, checkout, and order management.

This is where the story gets much bigger than one Google feature.

UCP is the moment agentic commerce starts looking less like demo theater and more like commerce infrastructure. The public UCP ecosystem shows names such as Google, Shopify, Etsy, Wayfair, Target, Walmart, Amazon, Microsoft, Meta, Salesforce, and Stripe. Google also says UCP was co-developed with Shopify, Etsy, Wayfair, Target, and Walmart, and endorsed by more than 20 others across the ecosystem including Adyen, American Express, Best Buy, Flipkart, Macy’s, Mastercard, Stripe, The Home Depot, Visa, and Zalando.

That partner list matters because commerce standards only matter when the ecosystem starts treating them as practical rails. One retailer experimenting with an AI assistant is interesting. Google, Shopify, Walmart, Amazon, Microsoft, Meta, Salesforce, Stripe, Visa, Mastercard, and Macy’s appearing around the same agentic commerce direction is a different signal.

The first visible pattern is already clear: Shopify shows how agents can search, cart, and check out through commerce infrastructure, while Macy’s shows how product discovery can become guided decision support inside a large retail catalog.

The real question is not whether shoppers will use agents, but whether brands have made their catalog, content, policies, inventory, identity, consent, and checkout reliable enough for agents to act on.

Shopify – commerce becomes agent-ready

Shopify makes agentic commerce feel real because it moves beyond product recommendations.

It gives agents three things they need to shop properly: a catalog, a cart, and checkout.

The Shopify Catalog lets agents search hundreds of millions of products with real-time inventory and localized pricing. Universal Cart lets a shopper hold products from multiple stores in one place. Checkout Kit loads the merchant’s checkout while keeping the experience native to the AI agent.

That is the shift.

The AI agent is no longer just answering, “Which product should I buy?” It can help find the product, compare it, hold it, and move the shopper toward purchase.

That changes what ecommerce operations means. Product titles, descriptions, categories, attributes, FAQs, return policies, structured data, stock, pricing, and checkout eligibility are no longer hygiene fields buried below the marketing layer. They become the evidence an agent uses to decide whether a product deserves to appear in the conversation.

This is the uncomfortable part. AI shopping does not reward the most beautiful homepage. It rewards the clearest machine-readable decision system.

If the category is weak, the product is harder for the agent to place. If the product description is thin, the agent has less to trust. If policy content is vague, the shopper’s risk question cannot be answered with confidence. If structured data is missing, the machine has to infer what the business should have made explicit.

For larger brands, Shopify is not the whole answer. It is the warning signal. If your website content, product data, images, ratings, customer service answers, consent rules, stock, pricing, and checkout logic do not work together, agents will see the gaps before consumers even reach your store.

Macy’s – when bad search becomes guided selling

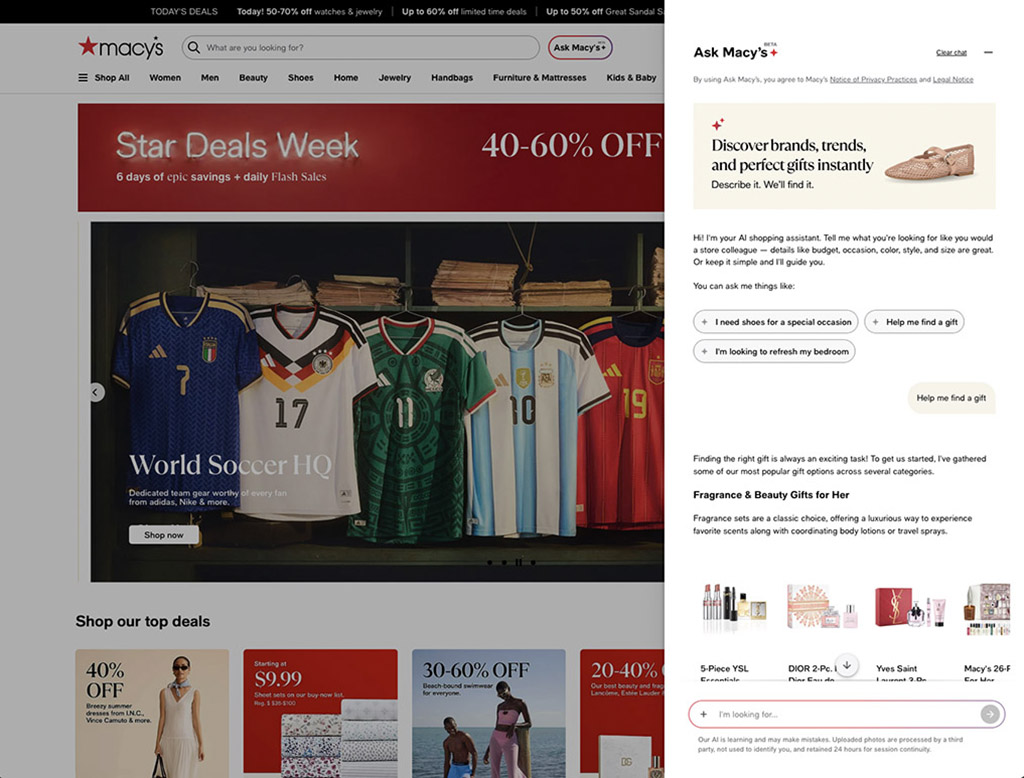
Macy’s website shows the Ask Macy’s AI shopping assistant guiding product discovery beside the main shopping page.

Macy’s is the better enterprise example because the starting problem is painfully familiar.

Large catalog. Too many SKUs. Search terms that do not match how consumers actually ask. Results pages that push the shopper back into work instead of helping them decide.

Ask Macy’s changes that pattern. Macy’s and Google turned product discovery into a guided chat, built with Google’s Gemini Enterprise for Customer Experience. The launch was not framed as a novelty chatbot. It was framed as a way to make digital shopping feel more guided, more personal, and closer to the help a shopper might expect in store.

The numbers are what make it worth paying attention to. It has been reported that Macy’s had more than 2.5 million SKUs in its product catalog, launched the tool from a small share of users to half of site users within a day, expanded to 100% a week later, and saw early beta revenue per visit about 4.75x higher among Ask Macy’s users than non-users.

That 4.75x figure should not be copied into a business case as a universal benchmark. It is early beta data, and it may be influenced by user selection, placement, product mix, measurement method, and intent quality.

But the signal is still useful. The commercial value was not that AI answered a question. The value was that the shopper stayed inside a decision path.

That is the difference between AI as a feature and AI as an operating model. A feature answers. An operating model connects the answer to assortment, availability, margin, policy, service, measurement, and conversion.

Enterprise readiness – agents will find the mess

Agentic commerce will not politely ignore weak foundations. It will expose them.

If your product data says one thing on the website, another thing in retailer feeds, and something else in customer service answers, the agent has a trust problem.

If stock, pricing, images, ratings, policies, and checkout rules are not aligned, the agent cannot confidently guide the shopper. It has to guess, skip, or hand off too early.

That is where many brands will struggle. Their consumer experience looks connected on the front end, but behind the scenes the journey is split across brand, ecommerce, CRM, media, legal, analytics, service, and IT.

The consumer will not care which team owns the gap. They will only see the broken answer, the missing product, the wrong promise, or the failed handoff.

Measurement also has to change. Agentic commerce is not only about which channel drove the click. It is about where the decision formed, what evidence the agent trusted, and whether the guided path created a better commercial outcome.

This is why the work is not only technical. It is operating-model work.

Brands need clear ownership for the data, answers, policies, offers, consent rules, measurement, and exceptions that agents will use. Without that ownership, agentic commerce becomes another unmanaged touchpoint.

Agentic commerce readiness – get the data in order

Do not start with every agent, every platform, and every possible integration. Start with the foundation agents will depend on: clean product data, clear policies, accurate stock, usable content, structured attributes, consent rules, service answers, and checkout logic.

That foundation cannot sit inside one team. Agentic commerce cuts across brand, ecommerce, CRM, media, legal, analytics, service, and IT. If those teams do not align what the agent can know, say, recommend, and trigger, the consumer will see the gaps immediately.

Takeaway: choose one high-value decision path, list the shopper questions the agent must answer, verify the product data and policy answers behind those questions, align ownership across the teams involved, connect only the safe commerce actions, and measure whether the guided path improves confidence, conversion, or service effort versus today’s search and checkout flow.


A few fast answers before you act

What is agentic commerce?

Agentic commerce is commerce where AI agents help shoppers move from intent to action, including discovery, comparison, recommendation, checkout, and post-purchase support.

Why does agentic commerce matter now?

It matters because the consumer journey is moving from page navigation to AI-guided decision-making.

What is Google UCP?

Google’s Universal Commerce Protocol is an open standard that helps AI surfaces, merchants, and payment providers work together across commerce actions such as discovery, checkout, and order management.

Why is Shopify important in this shift?

Shopify shows that agentic commerce is not just about better recommendations. Agents need clean product data, real-time inventory, cart logic, checkout handoff, and merchant rules they can safely act on.

What does the Macy’s example prove?

It does not prove that every AI shopping assistant will deliver a 4.75x revenue-per-visit lift. It proves that guided discovery can keep shoppers inside the decision path when search results alone are not enough.

What should enterprise teams do first?

Start with one high-value decision path, get the product data, policies, ownership, consent rules, and checkout logic behind it in order, then measure whether AI-guided discovery improves confidence, conversion, or service effort.